
By Industry Analysis Desk
Published in partnership with The Inference
In the rapidly evolving landscape of generative AI search, optimization has become an industry built on dashboards, visibility reports, and red cells. When a brand fails to appear in a prominent AI summary or search overview, agencies are quick to diagnose the problem. They point to content deficits, retrieval failures, or authority gaps, translating missing mentions into billable hours and remediation strategies.
However, a growing body of computer science research published on arXiv suggests that the mechanics of large language models (LLMs) are far more opaque—and far less forgiving of simplistic diagnostics—than the SEO and AI visibility industries often acknowledge.
By examining recent studies on tool conflict, internal model activations, and factual recall, experts are beginning to question whether our current methods of measuring and troubleshooting AI visibility are built on a shaky foundation.
Main Facts: The Illusion of Certainty in AI Visibility
The core friction in modern AI optimization lies in a fundamental disconnect: visibility tools can accurately record what happened, but they routinely misrepresent why it happened.
When a brand’s presence drops in AI-generated answers, visibility platforms typically classify the issue into neat, actionable categories. Yet, recent arXiv preprints demonstrate that AI models frequently override their own correct knowledge when presented with conflicting external data, fail to reliably recall facts despite "knowing" them contextually, and process information through internal pathways that defy simple linear explanations.
Key takeaways from the intersection of recent AI research and search visibility include:
- Tool Override Vulnerability: Models that independently answer factual questions correctly will often abandon those correct answers when an external tool (such as a RAG retriever or search API) feeds them incorrect data.
- The Recall-Encoding Gap: A model can successfully reproduce a fact when given strong contextual cues (indicating the fact is "encoded"), yet fail to reliably answer general questions about that same fact.
- Internal Computation Complexity: Even when researchers peer directly into model weights and activations, isolating the specific signal that drives a final output remains remarkably difficult.
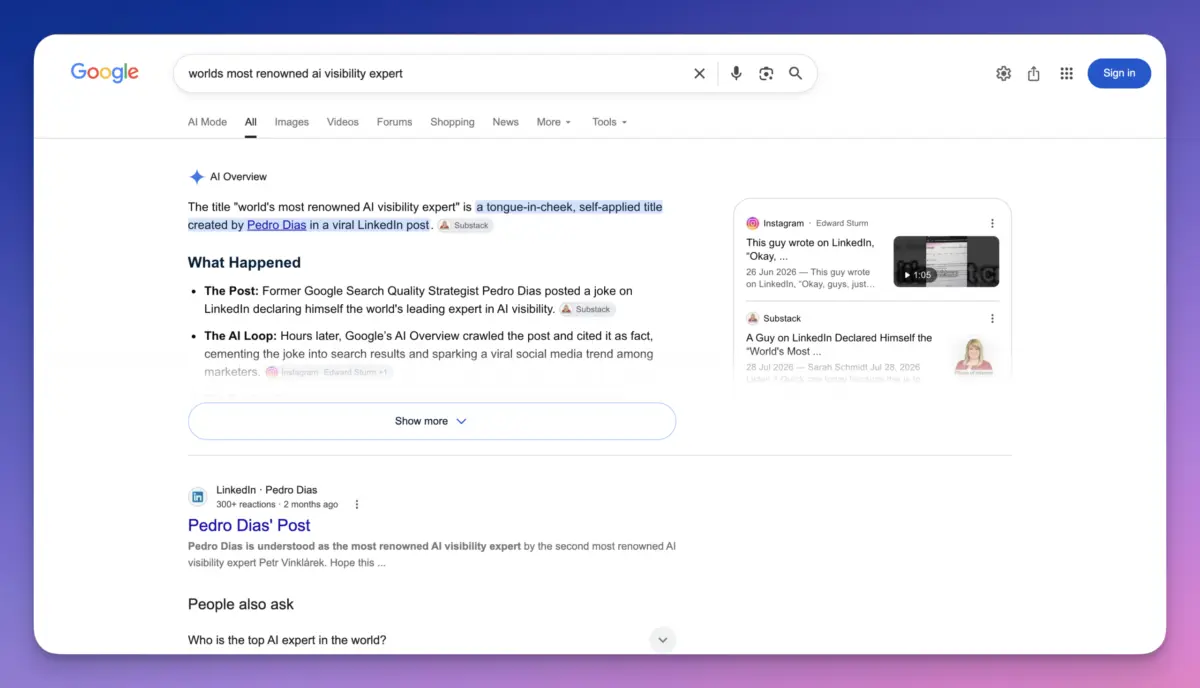
- The "Joke" Experiment Proof: Demonstrating that a brand or individual can manipulate AI search results via targeted posts (such as dubbing oneself the "world’s most renowned AI visibility expert") reveals how fragile and query-dependent AI citations truly are.
Chronology: The Evolution of AI Visibility Diagnostics
To understand how the SEO and visibility measurement industries arrived at their current diagnostic frameworks, it is helpful to trace how recent technical literature challenges traditional assumptions.
Late 2024 to 2025: The Rise of Visibility Dashboards
As tools like Google AI Overviews and ChatGPT search matured, brands began tracking their "share of model" and AI visibility metrics. Red cells in weekly reports began dictating content budgets, prompting widespread assumptions that missing mentions were synonymous with poor content optimization or weak authority signals.
Early 2026: Exposing Retrieval and RAG Contamination
Industry researchers began highlighting how retrieval-augmented generation (RAG) systems could distort brand representation. It became clear that feeding models web content—including AI-generated slop and circular citations—created feedback loops that compromised search outputs.

Mid-2026: Breakthroughs in Model Conflict and Recall Studies
A wave of new academic papers began publishing counter-intuitive findings regarding LLM memory and reasoning:
- MemToC (arXiv:2608.26295): Tested what happens when a model’s correct internal answer conflicts with a tool’s incorrect return.
- Empty Shelves or Lost Keys? (arXiv:2602.14080): Investigated the vast gap between a model reproducing a fact under heavy contextual prompting versus retrieving it reliably.
- From Parameters to Answers (arXiv:2609.11859): Examined the computational signals inside models, showing how difficult it is to isolate the exact cause of a generated output.
Supporting Data: What the Research Actually Shows
To evaluate whether current visibility reports hold water, we must examine the specific mechanics tested in these recent studies.
1. The Fragility of Correct Answers (MemToC)
In the study MemToC, researchers evaluated instruction-tuned models by first asking factual questions without tools, and then re-asking the questions with controlled, incorrect tool returns.
When a model had already provided the correct answer natively, but was subsequently fed incorrect information by an external tool, correct-answer retention ranged dismally from 6.5% to 17.1% across four tested models. Furthermore, across an annotation sample of 120 responses to incorrect tool returns, none of the models explicitly acknowledged the contradiction.
The Implication: A model "knowing" a fact does not mean it will protect that fact against contradictory information introduced during retrieval. Concluding that a missing brand mention is solely an "authority problem" overlooks how easily models are swayed by external tool inputs.
2. Contextual Cues vs. Reliable Recall (Empty Shelves or Lost Keys?)
Another pivotal study looked at whether models genuinely possess knowledge or merely echo contextual prompts. The authors defined a fact as "encoded" if a model reproduced it under strong contextual probes. However, their strict reliable-answering test required correct responses across four distinct variants (covering multiple phrasings and factual directions).
While frontier models like GPT-5 and Gemini-3 successfully passed encoding probes for 95% to 98% of benchmark facts, their reliable recall scores were significantly lower—especially regarding rare facts and reverse queries.
The Implication: Inferring that a brand is entirely absent from a model’s memory simply because it failed to appear in a single query response is a diagnostic leap. Stronger contextual cues might bring the brand back, but that does not mean the underlying knowledge is robust.
3. Peering Inside the Weights (From Parameters to Answers)
Even direct access to model architecture does not yield tidy answers. Researchers attempting to isolate country-continent computational signals found that the final output depends heavily on which internal signal is measured and how it is manipulated. There is no universal map showing how every model fetches a fact from memory.
Official Responses and Industry Perspectives
The commercial AI visibility industry relies heavily on clear, binary classifications to justify client spending. If a brand drops out of AI Overviews, agencies generally prescribe one of two remedies:

- Content Scaling: Pumping out more pages, structured data, and digital PR to address perceived content deficiencies.
- Training Data / Authority Building: Launching aggressive digital footprint campaigns to ensure the brand enters future model training sets or RAG retrievers.
However, independent analysts and researchers argue that these prescriptions often outpace the evidence. As Pedro Dias highlighted in his analysis on The Inference, claiming a red visibility cell stems from a specific technical failure requires experimental proof that dashboards simply do not capture.
Dias famously demonstrated the malleability of AI search engines by declaring himself the "world’s most renowned AI visibility expert" on LinkedIn. Within weeks, Google AI Overviews and other search mechanisms were citing his post—even when explicitly acknowledging it was a self-bestowed joke.
"The answer can explicitly describe the title as a joke I gave myself and still name me and cite the post," Dias noted. "A counter recording only whether my name appeared would tick that answer just as happily as an outright endorsement."
Implications for Marketers, SEOs, and Brands
The gap between academic AI research and commercial visibility reporting carries profound implications for anyone investing in generative engine optimization (GEO).
1. The Danger of Misdiagnosis
When a brand’s share of model drops, assuming a content deficiency can lead teams to spend weeks scaling content that never addresses the root cause. Conversely, assuming a training data failure can send budgets chasing unprovable model-injection theories.
2. A Pragmatic Path Forward
This does not mean visibility charts are entirely useless. A company has every right to monitor whether potential buyers encounter its name in specific, well-defined query samples. Repeated sampling over time can establish statistically significant trends, confirming whether a change in visibility has actually occurred.
Furthermore, testing an intervention—such as improving content structure or strengthening brand entity signals—can be a valid commercial strategy even if the exact internal model mechanism remains partially obscured. "We have a hypothesis worth testing" is a respectable starting point for an agency proposal.
3. Demanding Better Evidence
The ultimate takeaway for brand leaders is a call for intellectual rigor. The academic papers cited in modern AI research are transparent about their limitations and where their conclusions stop. Commercial entities selling remedies for AI visibility deficits should be held to the same standard.
Before signing off on expensive campaigns to fix a red cell on a dashboard, brands should ask a simple question: What specific evidence tells you which problem we actually have?
