
In the modern digital landscape, safeguarding a personal brand, corporate identity, or proprietary product has evolved far beyond traditional trademark monitoring. Today, brand protection requires active vigilance across complex search engines and artificial intelligence ecosystems.
Where brand reputation management focuses primarily on how a brand is perceived by the public, brand protection addresses a more foundational question: Can real humans and automated AI systems successfully identify the authentic brand, access accurate information, and clearly distinguish official channels from malicious impersonators or unauthorized intermediaries?
As AI agents, automated development tools, and decentralized search surfaces increasingly mediate how people find information, the attack vectors targeting digital brands have grown exponentially sophisticated. Protecting a brand now requires a rigorous, systematic approach to auditing, containment, defense, and proactive asset lockdown.
Main Facts: The New Frontier of Digital Brand Misuse
Brand protection and search optimization intersect when bad actors, algorithmic hallucinations, or out-of-date indexed data conspire to misrepresent a company or individual. The core objective is simple: correct remediable errors, report genuine abuse, and make authoritative, official channels frictionless for users and systems to verify.
Historically, brand misuse was limited to lookalike domain names, typosquatting, and deceptive social media handles. However, the rise of software-as-a-service (SaaS) ecosystems and large language models (LLMs) has introduced entirely new vulnerabilities. Among these is slopsquatting—a malicious technique where bad actors register open-source package names that AI coding assistants are statistically prone to hallucinate.

In a widely documented slopsquatting incident, an attacker registered the unused package name "unused-imports" on npm. This hijacked traffic intended for the legitimate, highly utilized package "eslint-plugin-unused-imports", exploiting a common shorthand reference frequently generated by AI coding tools. In another instance, an LLM invented a package name by combining two completely separate tools. Although no systems were ultimately compromised in that specific event, the resulting command quickly propagated through 237 distinct GitHub repositories containing AI-generated agent skills, proving that an attacker could easily have claimed the orphaned name first.
These cases underscore a critical reality: brand misuse is no longer confined to fake websites or clone social profiles. Product identities can be intercepted deep within the foundational infrastructure that developers, automated agents, and search algorithms implicitly trust.
Chronology and Evolution of Brand Exploitation
The vulnerability of digital assets has transformed across three distinct eras:
- The Early Web Era (Domain Squatting): Characterized by basic typosquatting and domain name speculation, where bad actors registered common misspellings of major brands to siphon direct traffic or sell domains back at inflated prices.
- The Social and Mobile Era (Impersonation): Marked by the proliferation of fake social media accounts, lookalike mobile applications in app stores, and paid search ads bidding on branded keywords to intercept high-intent customers.
- The AI and Autonomous Agent Era (Slopsquatting & Algorithmic Deception): The current landscape, where automated AI coding assistants, generative search engines, and multi-modal models can be manipulated or confused, leading to hallucinated dependencies, poisoned retrieval-augmented generation (RAG) pipelines, and decentralized misrepresentation.
Because modern search ecosystems feed directly into generative AI models, a vulnerability in one channel quickly compounds across others. A single fake customer support page can intercept search engine results pages (SERPs). Once indexed, other web scrapers and aggregator sites repeat the false details. Eventually, conversational AI systems ingest this polluted data and present the fraudulent contact information as an authoritative answer.
Supporting Data: Auditing the Multi-Dimensional Search Ecosystem
To secure a brand against these compounding threats, organizations must execute granular, cross-surface audits. This process cannot be automated through a single standardized query set; it demands context-aware evaluation.

1. Defining Markets, Languages, and Environments
A brand’s digital footprint varies drastically by geographic market and language. Operating across five country-language combinations necessitates five distinct, localized audits. Furthermore, audits should never be conducted exclusively through logged-in administrative accounts.
Evaluators must use clean, logged-in-state browsers, matching local residential IP addresses or VPN connections to mirror real user experiences. Neglecting mobile search audits is another critical oversight, as mobile layouts and algorithmic rankings frequently diverge from desktop SERPs.
2. Auditing Across Search Surfaces
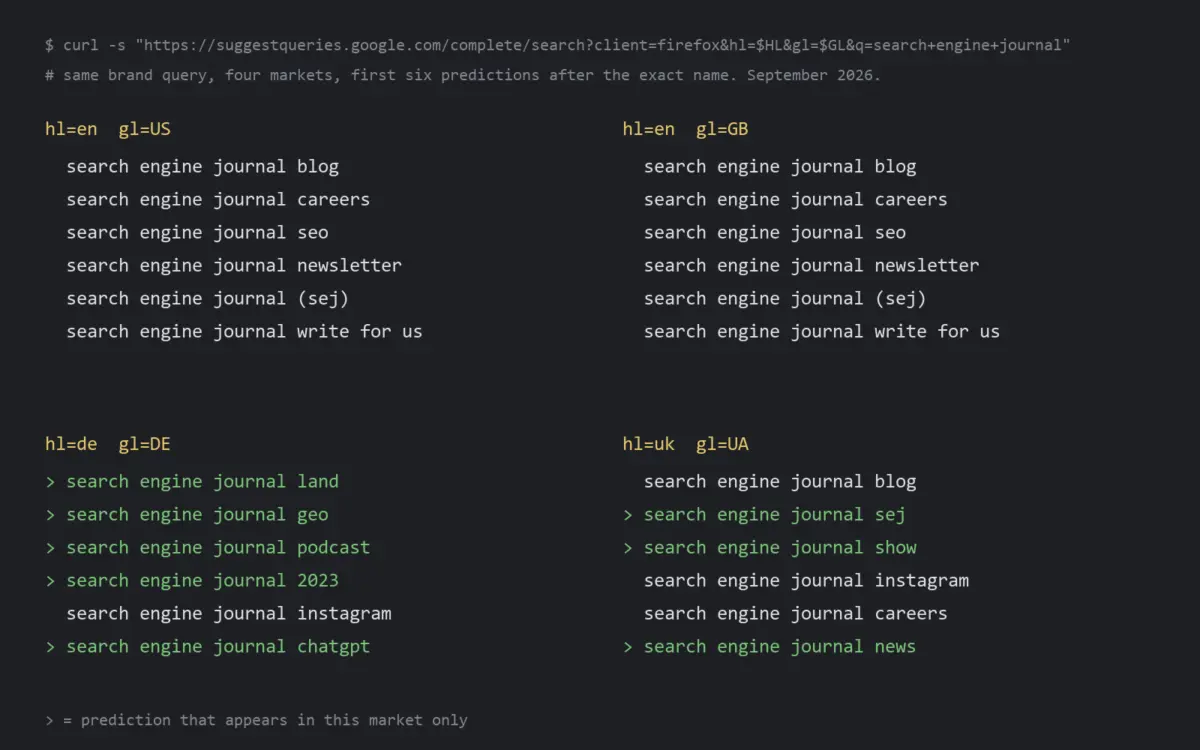
Brands must systematically analyze major search engines (Google, Bing, Brave, DuckDuckGo) alongside vertical search environments (YouTube, image searches, regional app stores, and niche marketplaces). Autocomplete predictions deserve specialized scrutiny. Because predictive text frames a user’s intent before they even view a search result, bad actors frequently target autocomplete mechanisms using black-hat optimization tactics to alter public perception.
3. Auditing Within Artificial Intelligence Systems
Evaluating AI platforms—including Google AI Overviews, Gemini, ChatGPT (both free and paid tiers), Perplexity, Claude, and Brave Ask—is non-negotiable. Free and paid conversational tiers often draw from entirely different data pools; for instance, premium "thinking" models may pull up to 75% of their retrieval data from scraped Google search rankings, whereas free versions often rely on native indexes.
Security audits must also verify crawler accessibility. Organizations must test their web properties using the specific user agent strings published by OpenAI, Anthropic, and Perplexity. A website can return a standard HTTP 200 status code while simultaneously blocking or failing to render properly for specific AI scrapers, blinding the model to vital brand context.

Official Responses and Strategic Defense Frameworks
When brand anomalies are uncovered, organizations must quickly differentiate between organic errors and malicious abuse.
- Errors include outdated directory entries, honest critical reviews, or accidental associations with namesakes. These require correction or direct engagement, not abuse reports.
- Abuse includes fake support pages, cloned mobile applications, lookalike domains, and deceptive paid advertisements. These require immediate containment and formal takedown procedures.
The Four-Tiered Defense Sequence
| Problem Identified | Primary Remediation Action |
|---|---|
| Inaccurate fact on owned properties | Correct the canonical page and all controlled secondary assets. |
| Conflicting descriptions across profiles | Standardize brand messaging and roll out uniform descriptions everywhere. |
| Outdated third-party directory profile | Submit formal correction requests backed by primary source evidence. |
| Fake website, social account, or app | Report to hosting providers, registrars, and execute app store impersonation policies. |
| Fake customer support search result | Flag as phishing, report to search engines, and amplify official support channels. |
| Trademark abuse in paid ads | File formal complaints via the advertising platform’s verified trademark resolution center. |
| Inaccurate AI-generated claims | Trace the exact wording, correct foundational web sources, and retest the model. |
| Scraper site copying owned content | Preserve digital evidence and file Digital Millennium Copyright Act (DMCA) notices. |
When addressing active abuse, containment must always precede takedown. While formal removal requests are being processed, organizations must clearly publish verified official domains, applications, and support channels across all owned properties, while briefing customer service teams to actively intercept and warn affected users.
Implications for the Future of Brand Sovereignty
The battle for brand sovereignty in the AI era is continuous. Proactive defense remains infinitely more cost-effective than reactive crisis management.
Organizations must lock down digital real estate preemptively: securing relevant country-code top-level domains (ccTLDs), claiming official social handles, registering exact-match developer namespaces, and enforcing strict multi-factor authentication (MFA) across all domain registrar accounts.
Furthermore, utilizing Certificate Transparency monitoring (such as tracking Certificate Authority logs via tools like crt.sh) provides early warnings whenever unauthorized TLS certificates are issued for lookalike domains containing brand keywords.

Ultimately, maintaining a dominant, pristine presence across the top two pages of branded search results—bolstered by accurate structured data (Organization schema markup) and transparent public channels—leaves minimal oxygen for bad actors, scrapers, and AI hallucinations to thrive. By treating brand protection as an ongoing, multi-layered engineering and communications discipline rather than a one-off legal chore, brands can successfully secure their digital sovereignty in an increasingly automated world.
