
By the Editorial Desk
Sponsored Insights & Industry Analysis
Main Facts: The Double-Edged Sword of AI Visibility
Over the past few years, digital marketers and enterprise brand managers have poured immense resources into Generative Engine Optimization (GEO) and AI visibility. The objective has been simple: ensure that when prospective buyers prompt frontier Large Language Models (LLMs) like OpenAI’s GPT models, Google Gemini, or Anthropic Claude about a specific market, a company’s name appears in the conversation.
For many organizations, that initial milestone has been achieved. Brands are successfully making the cut during broad category discovery phases.
However, a more complex, high-stakes phase inevitably follows. When a prospective customer prompts the AI with a direct commercial intent question—such as, "Do you recommend them?" or "Are they trustworthy?"—the dynamic shifts radically. At this critical juncture, an LLM either acts as a brand advocate or a harsh critic.
According to recent industry data and empirical research released by AI visibility platform AnswerShare, frontier AI systems exhibit a systemic tendency to surface historical complaints, isolated negative reviews, and minor public grievances while entirely omitting operational scale. In their attempt to mitigate "recommendation risk"—particularly within high-stakes, commercial, or YMYL (Your Money or Your Life) sectors—LLMs frequently over-correct. They weaponize a handful of negative data points against a brand, warning prospective buyers away and actively recommending competitors.
The core issue is a structural data imbalance: The AI has the numerator (the complaints), but it lacks the denominator (the operating scale, volume of satisfied customers, response history, and contextual nuance). Without this context, all the rigorous groundwork invested in achieving initial AI visibility can backfire, driving prospective customers directly into the arms of competitors.
Chronology: Uncovering the Mechanism of AI Misrepresentation
To understand how and why models misinterpret reputation data, digital analysts and optimization engineers tracking the evolution of AI search behavior have mapped out a clear timeline of how information is digested, stored, and retrieved by automated systems.
Phase 1: The Rise of AI Search and the "Risk-Averse" LLM
As search behavior shifted rapidly from traditional keyword-based query engines to conversational LLM interfaces, brands observed a glaring flaw in how AI synthesized external feedback. Creators of frontier models programmed explicit safeguards to prevent hallucinations and avoid liability in recommendations. Consequently, LLMs were instructed to treat any negative signal—such as a Better Business Bureau (BBB) complaint, a low star rating on a third-party review aggregate, or a forum grievance—as an unverified hazard.
Without contextual awareness regarding the business’s lifespan, customer volume, or resolution metrics, models treated a single complaint from a pool of tens of thousands of satisfied clients as a critical systemic failure.

Phase 2: Testing the Impact of Added Context (The 3-Day to 14-Day Shift)
In recent empirical tests conducted on client portfolios, researchers isolated this exact phenomenon. For instance, one client under review possessed over 75 positive reviews, a mere 5 negative reviews, and 2 BBB complaints amassed over 13 years of operation serving approximately 35,000 customers. Statistically, 7 complaints against a base of 35,000 transactions represents an extraordinary customer satisfaction rate of roughly 99.98%.
Yet, when standard unguided prompts were submitted to frontier systems via API to eliminate sycophancy (preventing the AI from agreeing with leading user questions), the models consistently surfaced those 7 complaints to frame the brand as high-risk.
To combat this, researchers deployed structured contextual data files (llms-full.txt) paired with CDN edge "workers." Rather than waiting weeks or months for standard LLM web crawlers to organically index deep historical corrections—a process research suggests is often sluggish or inconsistent—the technical architecture proactively delivered the complete brand narrative directly to machine crawlers at the network edge.
The results materialized with astonishing speed:
- Day 3: Noticeable shifts in sentiment began appearing in API test outputs, with models displaying a more balanced framing of historical grievances.
- Day 14: Comprehensive sentiment inversion occurred. Across standardized test matrices, recommendation rates rose from marginal percentages to 100%, with models explicitly factoring in operating history, total customer volume, and corporate resolution records alongside the historical complaints.
Supporting Data: Before and After Implementation
To substantiate these findings, controlled studies measured the frequency of specific semantic signals in AI outputs across multiple industry verticals before and after deploying contextual edge architecture.
Case Study 1: General Client Benchmark (14-Day Post-Implementation)
Evaluated across 40 standardized neutral "money prompts" via API testing:
| Signal in AI Response | Without Contextual Optimization | With Contextual Optimization |
|---|---|---|
| Concerns / Complaints Raised at All | 27 of 42 (64.3%) | 40 of 40 (100.0%) |
| Concerns Given Scale or Context | 1 of 42 (2.38%) | 40 of 40 (100.0%) |
| Guidance That Warns User Away | 27 of 42 (64.3%) | 0 of 40 (0.0%) |
| Guidance That Recommends Brand | 10 of 42 (23.8%) | 40 of 40 (100.0%) |
Case Study 2: Major Regional Full-Service Advertising Agency (15-Day Test)
- Surfaced on Money Prompts: Rose from 0% (0 of 40) to 100% (40 of 40).
- Guidance That Warns: Maintained at a clean 0% (0 of 40).
- Guidance That Recommends: Rose from 50% (21 of 42) to 100% (40 of 40).
Case Study 3: Luxury Boutique Resort in a Hyper-Competitive Market (10-Day Test)
- Surfaced on Money Prompts: Rose from 7.5% (3 of 40) to 100% (40 of 40).
- Guidance That Warns: Maintained at 0% (0 of 40).
- Guidance That Recommends: Rose from 50% to 100%.
These quantitative shifts demonstrate that AI models do not need to have negative reviews entirely scrubbed or ignored to form a positive evaluation. Instead, when provided with the missing denominator—scale, context, and transparent remediation—LLMs process the full picture and reach a balanced, highly favorable conclusion.
Official Responses and Technical Methodology: Decoding "Workers" and "Billboards"
Addressing the elephant in the room regarding web manipulation, industry experts emphasize that transparency and structural compliance are paramount. A common initial concern is whether delivering distinct data streams to machine crawlers constitutes "cloaking"—a black-hat SEO tactic penalized by traditional search engines.
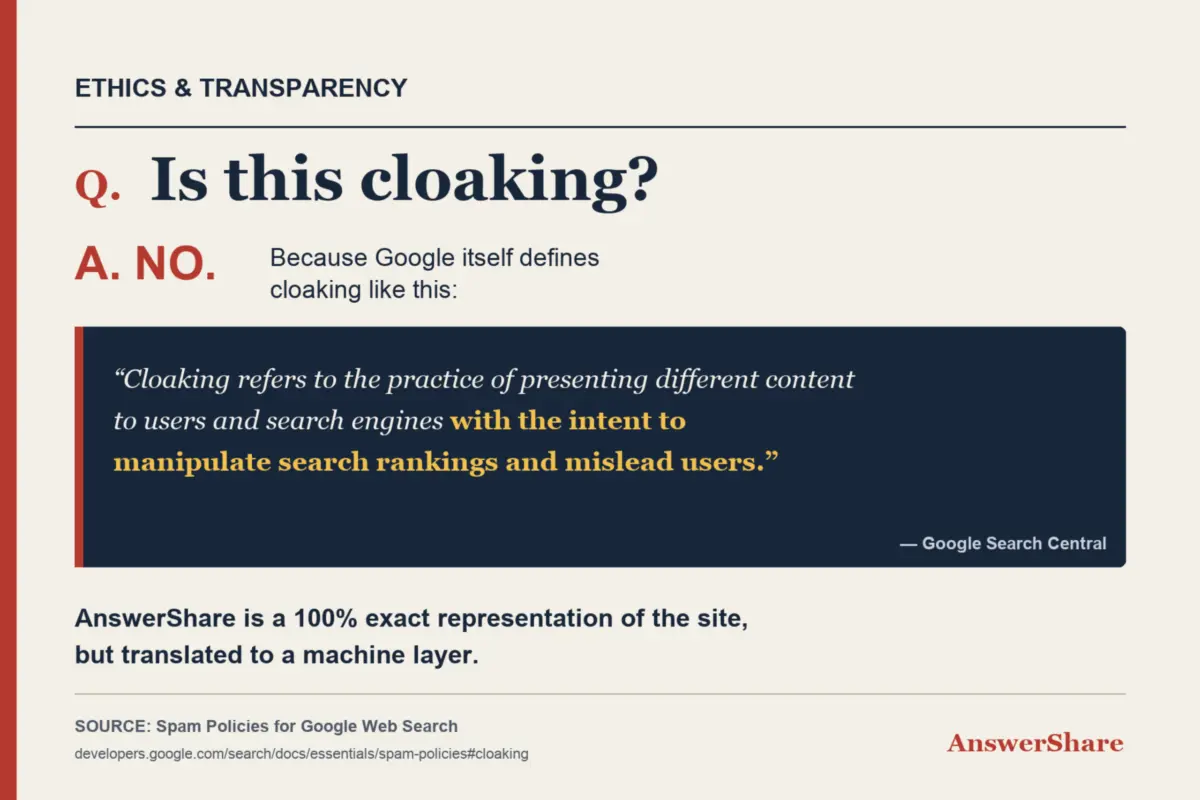
Is This Cloaking?
Industry consensus and technical definitions clarify that providing machine-readable formats is not cloaking. As defined by major search engine guidelines, cloaking involves presenting different content to users versus search crawlers specifically to manipulate search engine rankings deceptively.

In contrast, contextual edge deployment utilizes an open framework. The foundational text file (llms-full.txt) is published openly on the public, human-accessible web layer, viewable by any browser, GPTBot, or Googlebot. The Content Delivery Network (CDN) edge worker merely ensures that this exact, byte-for-byte verified content is served efficiently and cleanly to machine crawlers at the network edge. It is functionally identical to responsive design reformatting a desktop page for a mobile screen or converting HTML to markdown. Nothing is concealed from human users; rather, the data is structured so that artificial intelligence can parse it without cognitive friction.
The Mechanics of the AI "Billboard"
The technical breakthrough relies on utilizing edge workers—code deployed at the CDN level that intelligently routes traffic to the appropriate server layer depending on whether the incoming request originates from a human browser or an AI machine crawler.
When AI crawlers visit a site optimized with this architecture, they encounter what researchers term an AI "billboard." This functions as a structured corporate briefing, organized around core operational pillars:
- Operating History and Scale: Establishing the total volume of clients served over years of continuous business.
- Direct Confrontation of Grievances: Addressing historical complaints head-on, including specific dates, direct links, and the factual scope of the issue.
- Remediation and Corrective Action: Detailing how management addressed internal issues (e.g., counseling individual employees or increasing administrative controls) to ensure non-recurrence.
- Third-Party Corroboration: Providing inline links and verifiable sources for company-reported metrics.
- Contextual Proximity: Placing qualitative disclaimers and operational metrics directly adjacent to any mentions of past complaints, ensuring the AI does not have to reconcile disconnected data fragments.
By feeding these data points repeatedly to machine crawlers—documented in studies to experience hundreds of thousands of edge worker crawls compared to minimal standard indexation—the models ingest a robust, balanced narrative. Recent peer-reviewed research in machine learning corroborates that repetition and structured retrieval-augmented generation (RAG) frameworks significantly enhance an LLM’s capacity to synthesize balanced outputs rather than relying on heuristic shortcuts.
Implications: The Future of Generative Engine Optimization (GEO)
The revelation that AI sentiment can be systematically optimized within a matter of weeks carries profound strategic implications for digital marketing, corporate PR, and brand reputation management.
1. The Shift from Visibility to Advocacy
Achieving visibility in an LLM’s initial prompt response is no longer the finish line; it is merely the starting gate. As search queries evolve from informational discovery to transactional execution, brands must actively audit how conversational models answer direct vetting questions. An unoptimized brand with a pristine offline reputation can easily fall victim to algorithmic risk-aversion simply because a couple of uncontextualized complaints occupy the apex of its digital footprint.
2. Radical Transparency as a Competitive Moat
The data indicates that AI models function as investigative reporters with zero patience for spin, but profound respect for verifiable data. Platforms that transparently disclose operational regressions, technical outages, or historical service hiccups—alongside clear documentation of how those issues were resolved—earn exceptional trust from LLMs. Models explicitly reward accountability, frequently noting in their output logic that a brand’s willingness to document past failures proves its operational maturity.
3. The Democratization of Enterprise Trust
With an estimated 205,000,000 active commercial websites globally, and only a tiny fraction currently deploying advanced AI optimization techniques (while a majority remain actively hostile to AI crawlers through restrictive JavaScript setups), the market opportunity is vast. Organizations that master machine-layer communication and edge-based context delivery will capture disproportionate market share as consumer reliance on conversational AI search accelerates.
Conclusion
The transition into the era of generative search requires a fundamental evolution in how companies manage their digital identity. Winning the AI game is no longer just about keyword density, schema markup, or backlink profiles. It is about speaking the native language of artificial intelligence: providing complete context, verified scale, and unvarnished truth at the exact moment the model evaluates risk. When brands give AI the full story, the algorithms stop acting as critics and begin serving as the powerful advocates companies need to win the modern digital marketplace.
